QPRL · ICML 2025
QPRL: Learning Optimal Policies with Quasi-Potential Functions for Asymmetric Traversal
Separating potential differences from path-dependent costs to structure goal-reaching under asymmetric traversal.
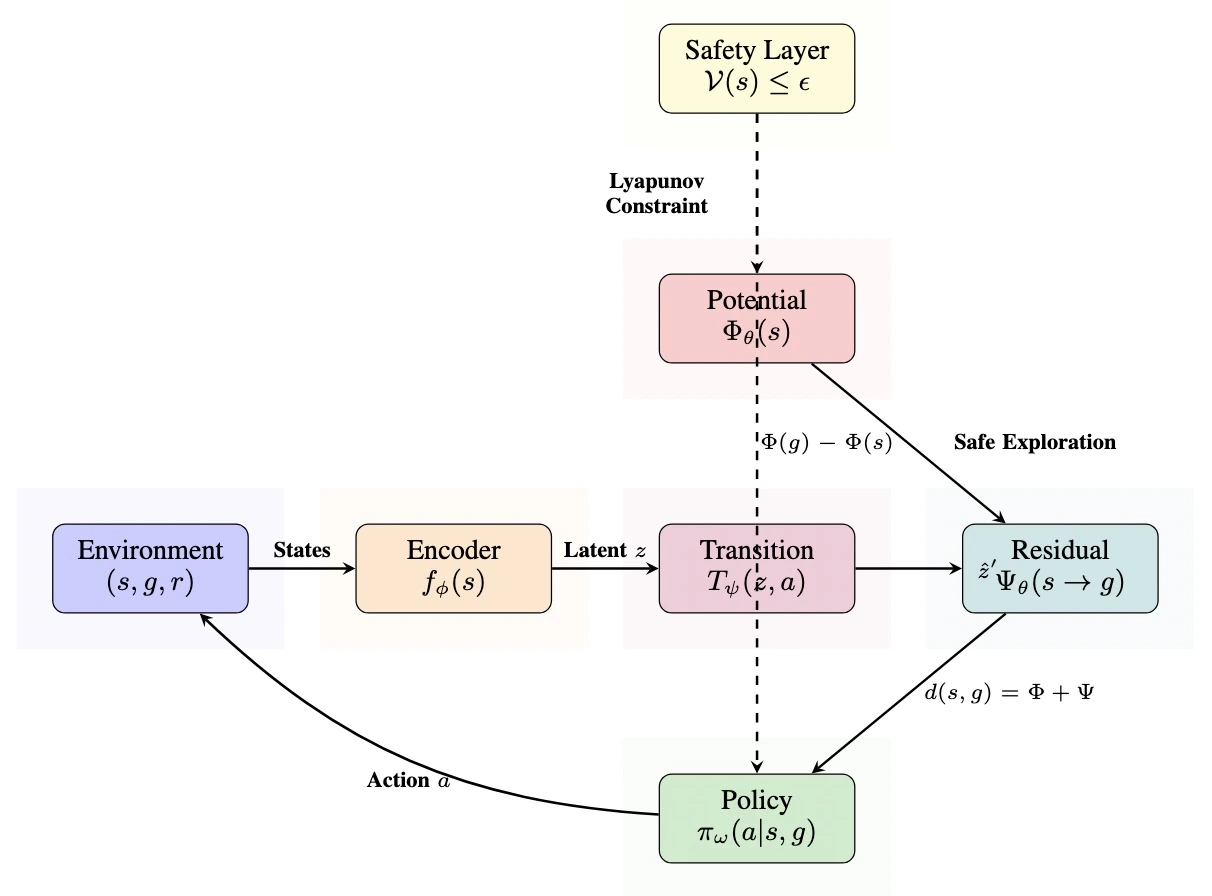
Overview
In goal-reaching tasks, a transition can be easy to make and difficult to undo. QPRL studies a representation of traversal cost that explicitly accounts for that directional structure.
The method decomposes cost into a potential difference and a path-dependent residual. This structure is combined with a Lyapunov-based constraint during policy learning.